Are Dentures Better Than Bad Teeth . Dentures are generally the poorest quality of tooth replacement. Help with eating and chewing; Foods That Are Bad for Your Teeth Jefferson Dental from www.jeffersondentalclinics.com In this case, a denture would be better. Reduce wrinkles fill lips and skin out around month area; There are a few ways you can make your dentures fit better.
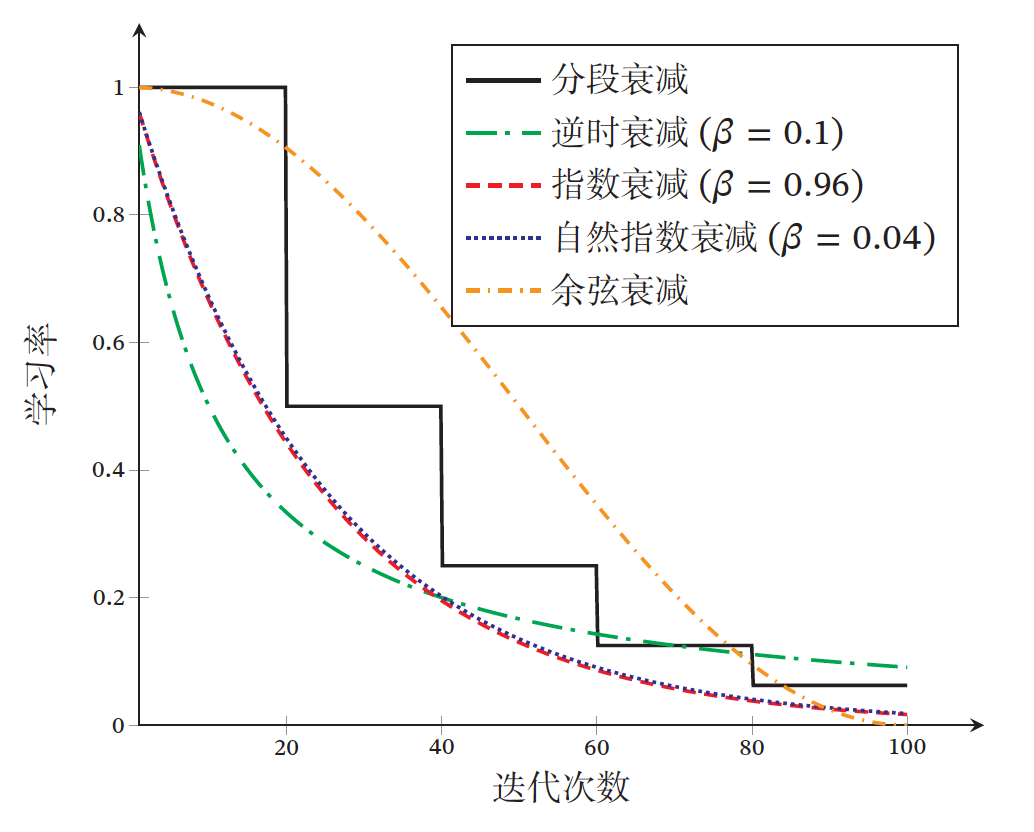
Cosine Decay Learning Rate. The learning rates are decayed for init_decay_epochs from initial values passed to optimizer to the min_decay_lr using cosine function. Exponential decay [for learning rate] we’re gradually reducing the learning rate to 95% of the previous value every 128 steps.
【读书笔记】《神经网络与深度学习》 网络优化与正则化 惟愿此心无怨尤 from bingqiangzhou.github.io
To learning_rate_base for warmup_steps, then transitions to a cosine decay: If the learning rate is set solely by this scheduler, the learning rate at each step becomes: (verified 6 hours ago) oct 07, 2020 · the cosine learning rate decay involves reductions and restarts of learning rates over the course of training.
This Strongly Determines The Decay Profile:
Asked jul 16 '20 at 9:26. Stochastic gradient descent with warm restarts by ilya loshchilov et al. See [loshchilov & hutter, iclr2016], sgdr:
In This Schedule, The Learning Rate Grows Linearly From Warmup_Learning_Rate:
Follow this question to receive notifications. When training a model, it is often recommended to lower the learning rate as the training progresses. Decaying the learning rate is simulated annealing.
False } So I Would Assume The Learning Rate Would Go Up To 0.08 Until Step 250, Afterwards It Would Slowly Go Down Again Until End Of Training At Step.
The learning rates are decayed for init_decay_epochs from initial values passed to optimizer to the min_decay_lr using cosine function. Stochastic gradient descent with warm restarts. We propose an alternative procedure;
(5), Where One Run (Or Cycle) Is Typically One Or Several Epochs.
It would be something like setting a configuration like the highest learning, the lowest learning, and Cosine annealing learning rate as described in: To learning_rate_base for warmup_steps, then transitions to a cosine decay:
Then The Training Process Will Begin During A.
Applies cosine decay to the learning rate. Stochastic gradient descent with warm restarts. # compute the new learning rate based on polynomial decay.


Comments
Post a Comment